Broker complaint learning scenario studio
Practice the behavior behind complaint lessons.
- For
- Agency quality trainers
- Solves
- Complaint findings do not become practical training.
- Delivers
- Trainer-reviewed learning pack
- Built in
- about 5 weeks of creation time, MVP in 6 days
- Investment
- $13,000 for the MVP, $44,000 for the full product
- Run it
- Inside your business, or as part of your offer to clients
What it does
For agency quality trainers, turn approved anonymized findings and service rules into trainer-reviewed learning pack.
- Create boundary scenarios.
- Test response reasoning.
- Link corrective actions.
- Link proposed outputs to original source records.
- Capture reviewer corrections and approval.
- Export a versioned trainer-reviewed learning pack.
What goes in, what comes out
- Approved anonymized findings
- Service rules
AI drafts, people review. Interactive practice or facilitated workshop platform.
- Trainer-reviewed learning pack
How it works
The workflow
- InStart with
Approved anonymized findings and service rules
- 1
The buyer creates a project
- 2
Supplies approved anonymized findings and service rules
- 3
Confirms scope and access
- OutFinish with
Trainer-reviewed learning pack
AI does the heavy lifting, people stay in charge
AI assists these bounded tasks: create boundary scenarios; test response reasoning; link corrective actions. Use only approved anonymized findings and service rules and preserve uncertainty in trainer-reviewed learning pack. Keep model suggestions separate from verified facts. Link factual outputs to authorized input evidence and show missing information explicitly. Use deterministic checks for counts, dates, identifiers and arithmetic where applicable. A designated reviewer validates consequential outputs and signs off the delivered result.
What your team sees
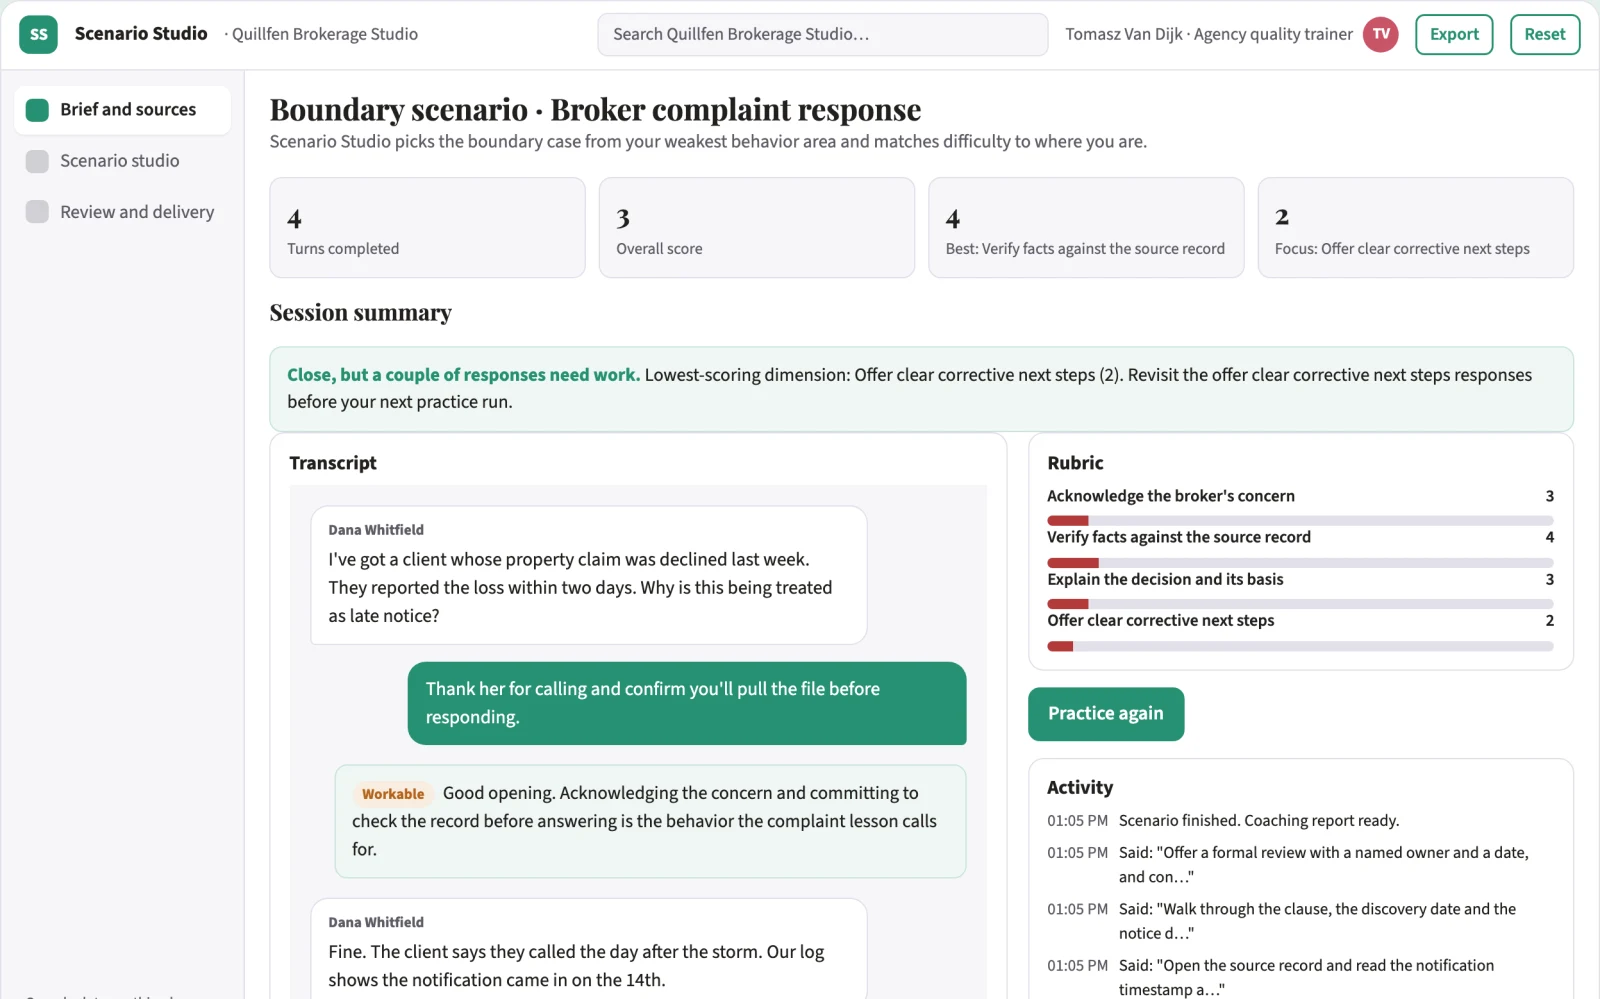
Key screens: Brief and sources, Broker complaint learning scenario studio, Review and delivery. Use a scenario catalog with clear goals and difficulty settings. The main session area supports text, optional voice and visible context. Follow it with a replay or decision map, annotated feedback and a next-practice plan. Facilitators can author scenarios and review participant-selected sessions. Open with brief and sources; move into broker complaint learning scenario studio for the detailed task; finish in review and delivery for review and handoff. Show the source record, uncertainty and approval status beside each proposed output.
Accounts and administration
Participant-controlled session sharing, scenario versions, facilitator tools, replay history, rubric calibration, practice goals and exportable feedback. Include organization-scoped access, named project owners, review queues, usage limits, export history and retention settings. Never reuse private customer material for other accounts without permission.
Integrations and data access
Broker-approved policy documents, case records and carrier requirements. Learning portals, calendar scheduling and authorized session exports. Make recording, sharing and retention controls explicit in the product. Begin with uploads and exports of approved anonymized findings and service rules. Any named system or connector is a candidate requiring current access and compatibility checks; no live connection is included by default.
How we build it
We build with our own AI software development factory, so most implementations take days to a few weeks of creation time, not months. You see working software at every step, and exact timing depends on availability.
- 1
Scoping call
Day 1Thirty minutes on your process, your data and how you want to run it: for your own team, or for your clients. You get a fixed scope and price for the MVP.
- 2
MVP
6 daysOne buyer segment, one recurring use case; first modules: create boundary scenarios; test response reasoning. Manual review in the loop. Built by our AI software factory.
- 3
Paid pilot
7 daysAccounts, roles, review states, audit trail and the first integration, hardened for two to three paying pilot customers.
- 4
Full product
3 weeksSelf-serve onboarding, billing, monitoring and the wider integration set.
- 5
Run and improve
MonthlyWe host, monitor and improve it for a fixed monthly fee, or hand it over to your team. How the retainer works.
Why we start with an MVP
An MVP, or minimum viable product, is the smallest version that your users can actually work with. It is not a cheap version of the full solution. It is a test, built to answer the questions that decide whether the rest is worth building.
- Pick the riskiest assumption. Here: will agency quality trainers use it to solve "complaint findings do not become practical training"?
- Build only what tests it. One team, one use case, a few core modules. People do the rest by hand for now.
- Run a paid pilot. Agree the acceptance criteria, input limits and reviewer responsibilities before starting.
- Measure, then decide. Track corrected scenario responses; reviewer correction minutes; buyer acceptance and repeat purchase. Then expand, change course or stop, with evidence instead of opinions.
MVP scope for this solution. Costed pilot: One organization, one defined input format and one representative pilot batch using approved anonymized findings and service rules. Professional judgment, physical inspections, live external actions and production certification remain outside this prototype. Start with one buyer organization and a bounded set of representative inputs. Implement the first two modules: create boundary scenarios; test response reasoning. Support the third task through an assisted review queue: link corrective actions. Handle the remaining required functions manually until validated. Include input upload, source references, user correction, a reviewer approval step and export of trainer-reviewed learning pack. Authentication, account isolation, deletion controls and basic operational logging are included. Specialized production certification, live write integrations and broader rollout are not included unless explicitly stated.
After the MVP. After paying customers repeatedly accept trainer-reviewed learning pack, automate link proposed outputs to original source records; capture reviewer corrections and approval; export a versioned trainer-reviewed learning pack. Add one tested read integration, reusable customer configuration and scheduled repeat delivery. Increase supported formats or teams only when evaluation cases and reviewer capacity cover the new scope. One organization, one defined input format and one representative pilot batch using approved anonymized findings and service rules. Professional judgment, physical inspections, live external actions and production certification remain outside this prototype.
What the build depends on. Scenario state management, coherent dialogue, explicit rubrics, session replay and reviewer feedback. Voice interaction adds latency and audio QA requirements. Obtain representative authorized inputs, an agreed review rubric and a buyer-side owner. Specific scope: One organization, one defined input format and one representative pilot batch using approved anonymized findings and service rules. Professional judgment, physical inspections, live external actions and production certification remain outside this prototype.
Investment
A planning range to start the conversation, not a quote. You pay per phase, so you can stop after the MVP.
- Phase 1
MVP
One buyer segment, one recurring use case; first modules: create boundary scenarios; test response reasoning. Manual review in the loop.
- Phase 2
Paid pilot
Accounts, roles, review states, audit trail and the first integration, hardened for two to three paying pilot customers.
- Phase 3
Full product
Self-serve onboarding, billing, monitoring and the wider integration set.
Indicative total, MVP to full product$44,000about 5 weeks of creation time · start with the MVP from $13,000
Running costs per month
A rough indication of monthly hosting and AI model costs once it is live, not tested. Real costs depend on usage, file sizes and the models chosen.
| Stage | Hosting and infrastructure | AI usage | Total per month |
|---|---|---|---|
| MVP and paid pilotabout 3 customers | $50–$100 | $50–$110 | $100–$210 |
| Full productabout 50 customers | $190–$380 | $420–$840 | $610–$1,220 |
Run it or resell it
For your own team
Agency quality trainers run it inside the business: approved anonymized findings and service rules in, trainer-reviewed learning pack out, reviewed by your people.
As part of your offer
Agencies, consultancies and software companies can offer it to their own clients under their brand. We build and maintain it; you sell and deliver it.
Your brand, or this one
Run it under your own brand, or start from this concept style.
- primary
#279173 - accent
#c95468 - surface
#e4f1ed - ink
#22201e
- Headings
- Playfair Display
- Text
- Source Sans 3
- Voice
- Reassuring, clear, no small print
Selling it to your own clients: the go-to-market playbook
Pricing to test
Test USD 300-1,500 for a facilitated team pilot, or USD 20-80 per participant monthly for self-serve practice with limited usage. Bespoke workshops and expert coaching are separately scoped. Pricing is hypothetical. For this buyer, package the first sale around prepare a sample trainer-reviewed learning pack from a small authorized set of approved anonymized findings and service rules and the defined trainer-reviewed learning pack. Record actual review effort before offering a recurring allowance. The commercial pilot fee is distinct from the platform development budget.
Message to test
Practice the behavior behind complaint lessons. Demonstrate the result with prepare a sample trainer-reviewed learning pack from a small authorized set of approved anonymized findings and service rules for agency quality trainers. Use a concrete before-and-after example without promising unmeasured savings.
Where to find buyers
Broker associations and insurance service consultants
Lead magnet
Prepare a sample trainer-reviewed learning pack from a small authorized set of approved anonymized findings and service rules
The first 30 days
- Week 1: interview five prospective buyers from agency quality trainers and inspect how they handle complaint findings do not become practical training.
- Week 2: prepare prepare a sample trainer-reviewed learning pack from a small authorized set of approved anonymized findings and service rules using authorized or synthetic material.
- Week 3: share the demonstration through broker associations and insurance service consultants and seek one bounded paid pilot.
- Week 4: measure corrected scenario responses; reviewer correction minutes; buyer acceptance and repeat purchase, review delivery effort and ask for a repeat purchase. This is a validation schedule, not a promise that the full product can be built in thirty days.
Paid pilot
Agree the acceptance criteria, input limits and reviewer responsibilities before starting. Run prepare a sample trainer-reviewed learning pack from a small authorized set of approved anonymized findings and service rules and deliver trainer-reviewed learning pack. Compare corrected scenario responses; reviewer correction minutes; buyer acceptance and repeat purchase with the buyer's current process on comparable cases; include corrections, missed issues and reviewer time. Seek payment and repeat use. Stop or revise the scope if data access, accuracy or unit economics fail.
Success metrics
Corrected scenario responses; reviewer correction minutes; buyer acceptance and repeat purchase
Retention and expansion
Build repeat use around trainer-reviewed learning pack. Save approved configurations and review decisions with permission, revisit unresolved exceptions and show progress on corrected scenario responses; reviewer correction minutes; buyer acceptance and repeat purchase. Offer a recurring volume allowance after repeat demand; expand to adjacent tasks only when the buyer asks and delivery quality remains acceptable.
Why clients would pick it
Realistic domain scenarios, qualified facilitator relationships and reviewed examples of useful feedback and successful practice. For this concept, accumulate permissioned examples and reviewer corrections around practice the behavior behind complaint lessons. The durable asset is reliable task-specific execution and trusted customer configuration, not access to a general-purpose AI model.
Alternatives and positioning
Human coaching, workshops, static courses, roleplay with colleagues and general chat tools. Position this concept around practice the behavior behind complaint lessons. Compare it against the customer's current process on the same representative task. This is proposed differentiation; no exhaustive competitor study or uniqueness claim has been established.
Main delivery costs
Scenario design, voice processing if used, model interaction length, facilitator review, rubric calibration and learner support. Initial validation additionally budgets for representative sample preparation, interviews with agency quality trainers, and qualified domain review of trainer-reviewed learning pack. Track model usage, storage, reviewer minutes, exception handling and customer support per accepted deliverable.
Safeguards
Separate document preparation from coverage, underwriting and claims decisions. Authorized professionals review policy meaning and customer commitments. One organization, one defined input format and one representative pilot batch using approved anonymized findings and service rules. Professional judgment, physical inspections, live external actions and production certification remain outside this prototype. Require appropriate access and publication approval. Preserve source material, label AI drafts and make corrections traceable. Measure false positives and missed cases alongside speed.