Data contract drift watch
Connect schema drift to documented consumers.
- For
- Analytics engineering teams
- Solves
- Upstream schema changes silently break downstream assumptions.
- Delivers
- Data contract change report
- Built in
- about 3 weeks of creation time, MVP in 3 days
- Investment
- $17,000 for the MVP, $50,000 for the full product
- Run it
- Inside your business, or as part of your offer to clients
What it does
For analytics engineering teams, turn approved schemas and pipeline dependency metadata into data contract change report.
- Compare schema versions.
- Map dependent fields.
- Classify contract changes.
- Draft owner alerts.
- Track approved exceptions.
- Export migration notes.
What goes in, what comes out
- Approved schemas
- Pipeline dependency metadata
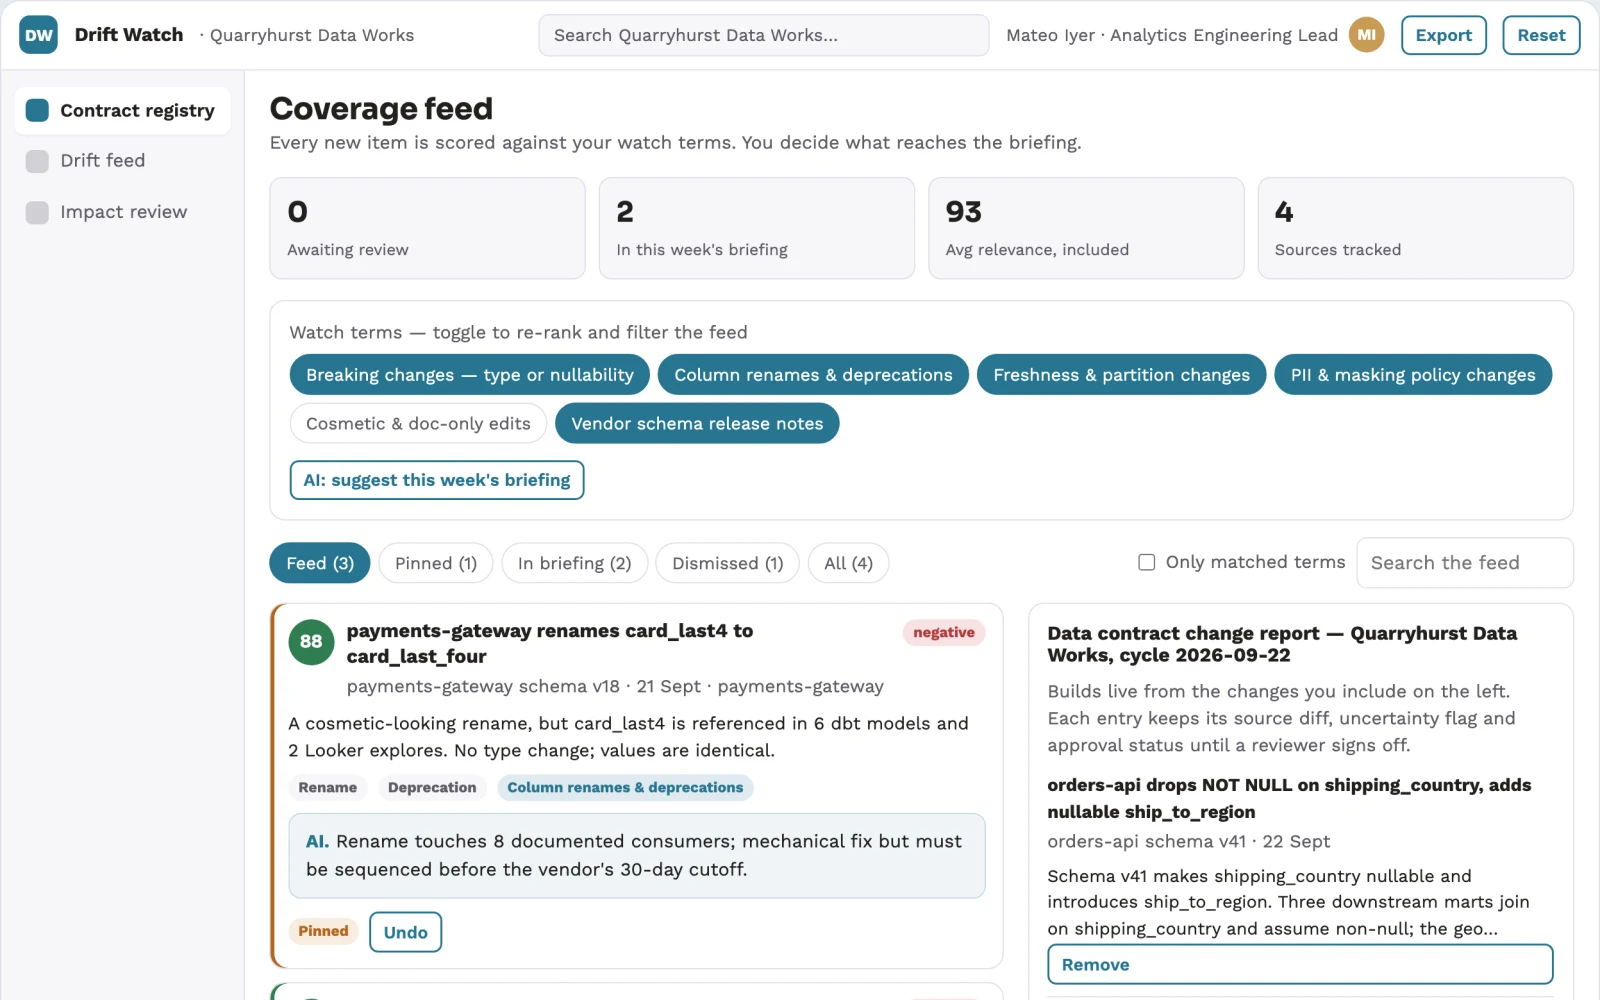
AI drafts, people review. Watchlist, change detection and briefing subscription.
- Data contract change report
How it works
The workflow
- InStart with
Approved schemas and pipeline dependency metadata
- 1
The buyer creates a project
- 2
Supplies approved schemas and pipeline dependency metadata
- 3
Confirms scope and access
- OutFinish with
Data contract change report
AI does the heavy lifting, people stay in charge
Explain change impact without accessing production records. Keep model suggestions separate from verified facts. Link factual outputs to authorized input evidence and show missing information explicitly. Use deterministic checks for counts, dates, identifiers and arithmetic where applicable. A designated reviewer validates consequential outputs and signs off the delivered result.
What your team sees
Key screens: Contract registry, Drift feed, Impact review. Use a watchlist with source health and last-checked dates, a chronological change feed, and a reviewable briefing editor. Display original evidence beside each alert. Let users mute irrelevant topics and record whether a change led to action. Open with contract registry; move into drift feed for the detailed task; finish in impact review for review and handoff. Show the source record, uncertainty and approval status beside each proposed output.
Accounts and administration
Watchlist ownership, source health, dated evidence, deduplication, topic filters, editorial review, delivery preferences and alert feedback. Include organization-scoped access, named project owners, review queues, usage limits, export history and retention settings. Never reuse private customer material for other accounts without permission.
Integrations and data access
Authorized repositories, technical documentation, application APIs and logs. Permitted feeds, published document sources, email digests and internal briefing channels. Verify collection rights and source reliability before selling coverage commitments. Begin with uploads and exports of approved schemas and pipeline dependency metadata. Any named system or connector is a candidate requiring current access and compatibility checks; no live connection is included by default.
How we build it
We build with our own AI software development factory, so most implementations take days to a few weeks of creation time, not months. You see working software at every step, and exact timing depends on availability.
- 1
Scoping call
Day 1Thirty minutes on your process, your data and how you want to run it: for your own team, or for your clients. You get a fixed scope and price for the MVP.
- 2
MVP
3 daysOne buyer segment, one recurring use case; first modules: compare schema versions; map dependent fields. Manual review in the loop. Built by our AI software factory.
- 3
Paid pilot
4 daysAccounts, roles, review states, audit trail and the first integration, hardened for two to three paying pilot customers.
- 4
Full product
6 daysSelf-serve onboarding, billing, monitoring and the wider integration set.
- 5
Run and improve
MonthlyWe host, monitor and improve it for a fixed monthly fee, or hand it over to your team. How the retainer works.
Why we start with an MVP
An MVP, or minimum viable product, is the smallest version that your users can actually work with. It is not a cheap version of the full solution. It is a test, built to answer the questions that decide whether the rest is worth building.
- Pick the riskiest assumption. Here: will analytics engineering teams use it to solve "upstream schema changes silently break downstream assumptions"?
- Build only what tests it. One team, one use case, a few core modules. People do the rest by hand for now.
- Run a paid pilot. Agree the acceptance criteria, input limits and reviewer responsibilities before starting.
- Measure, then decide. Track unannounced breaking changes and triage time. Then expand, change course or stop, with evidence instead of opinions.
MVP scope for this solution. Costed pilot: Metadata-only pilot with deterministic schema comparisons. Start with one buyer organization and a bounded set of representative inputs. Implement the first two modules: compare schema versions; map dependent fields. Support the third task through an assisted review queue: classify contract changes. Handle the remaining required functions manually until validated. Include input upload, source references, user correction, a reviewer approval step and export of data contract change report. Authentication, account isolation, deletion controls and basic operational logging are included. Specialized production certification, live write integrations and broader rollout are not included unless explicitly stated.
After the MVP. After paying customers repeatedly accept data contract change report, automate draft owner alerts; track approved exceptions; export migration notes. Add one tested read integration, reusable customer configuration and scheduled repeat delivery. Increase supported formats or teams only when evaluation cases and reviewer capacity cover the new scope. Metadata-only pilot with deterministic schema comparisons.
What the build depends on. Reliable permitted source access, change history, publication dates, deduplication and editorial QA. Coverage limits and inaccessible sources must be visible. Obtain representative authorized inputs, an agreed review rubric and a buyer-side owner. Specific scope: Metadata-only pilot with deterministic schema comparisons.
Investment
A planning range to start the conversation, not a quote. You pay per phase, so you can stop after the MVP.
- Phase 1
MVP
One buyer segment, one recurring use case; first modules: compare schema versions; map dependent fields. Manual review in the loop.
- Phase 2
Paid pilot
Accounts, roles, review states, audit trail and the first integration, hardened for two to three paying pilot customers.
- Phase 3
Full product
Self-serve onboarding, billing, monitoring and the wider integration set.
Indicative total, MVP to full product$50,000about 3 weeks of creation time · start with the MVP from $17,000
Running costs per month
A rough indication of monthly hosting and AI model costs once it is live, not tested. Real costs depend on usage, file sizes and the models chosen.
| Stage | Hosting and infrastructure | AI usage | Total per month |
|---|---|---|---|
| MVP and paid pilotabout 3 customers | $30–$60 | $50–$100 | $80–$160 |
| Full productabout 50 customers | $110–$210 | $350–$700 | $460–$910 |
Run it or resell it
For your own team
Analytics engineering teams run it inside the business: approved schemas and pipeline dependency metadata in, data contract change report out, reviewed by your people.
As part of your offer
Agencies, consultancies and software companies can offer it to their own clients under their brand. We build and maintain it; you sell and deliver it.
Your brand, or this one
Run it under your own brand, or start from this concept style.
- primary
#277591 - accent
#c99a54 - surface
#e4edf1 - ink
#22201e
- Headings
- Sora
- Text
- Work Sans
- Voice
- Technical, direct, no hype
Selling it to your own clients: the go-to-market playbook
Pricing to test
Test USD 100-500 monthly for a narrow shared briefing, or USD 750-2,500 monthly for bespoke analyst coverage. Licensed source access and unusual collection requirements are extra. Prices require validation. For this buyer, package the first sale around monitor one sample pipeline and the defined data contract change report. Record actual review effort before offering a recurring allowance. The commercial pilot fee is distinct from the platform development budget.
Message to test
Connect schema drift to documented consumers. Demonstrate the result with monitor one sample pipeline for analytics engineering teams. Use a concrete before-and-after example without promising unmeasured savings.
Where to find buyers
Data engineering communities and analytics consultancies
Lead magnet
Monitor one sample pipeline
The first 30 days
- Week 1: interview five prospective buyers from analytics engineering teams and inspect how they handle upstream schema changes silently break downstream assumptions.
- Week 2: prepare monitor one sample pipeline using authorized or synthetic material.
- Week 3: share the demonstration through data engineering communities and analytics consultancies and seek one bounded paid pilot.
- Week 4: measure unannounced breaking changes and triage time, review delivery effort and ask for a repeat purchase. This is a validation schedule, not a promise that the full product can be built in thirty days.
Paid pilot
Agree the acceptance criteria, input limits and reviewer responsibilities before starting. Run monitor one sample pipeline and deliver data contract change report. Compare unannounced breaking changes and triage time with the buyer's current process on comparable cases; include corrections, missed issues and reviewer time. Seek payment and repeat use. Stop or revise the scope if data access, accuracy or unit economics fail.
Success metrics
Unannounced breaking changes and triage time
Retention and expansion
Build repeat use around data contract change report. Save approved configurations and review decisions with permission, revisit unresolved exceptions and show progress on unannounced breaking changes and triage time. Offer a recurring volume allowance after repeat demand; expand to adjacent tasks only when the buyer asks and delivery quality remains acceptable.
Why clients would pick it
A curated source network, historical change archive and buyer-specific relevance judgments within a narrow topic. For this concept, accumulate permissioned examples and reviewer corrections around connect schema drift to documented consumers. The durable asset is reliable task-specific execution and trusted customer configuration, not access to a general-purpose AI model.
Alternatives and positioning
Newsletters, search alerts, analysts and general media or website monitoring tools. Position this concept around connect schema drift to documented consumers. Compare it against the customer's current process on the same representative task. This is proposed differentiation; no exhaustive competitor study or uniqueness claim has been established.
Main delivery costs
Source licensing, collection reliability, change processing, analyst verification, missed-signal review and digest production. Initial validation additionally budgets for test pipelines and engineer review. Track model usage, storage, reviewer minutes, exception handling and customer support per accepted deliverable.
Safeguards
Protect secrets, customer data and source code. Use controlled environments, technical review and a recoverable deployment process. Metadata-only pilot with deterministic schema comparisons. Require appropriate access and publication approval. Preserve source material, label AI drafts and make corrections traceable. Measure false positives and missed cases alongside speed.