Usability research assistant
Observed behavior and source clips remain attached to every usability finding.
- For
- Design teams running frequent user tests
- Solves
- Session evidence is difficult to turn into actionable findings.
- Delivers
- Evidence-linked usability findings
- Built in
- about 3 weeks of creation time, MVP in 3 days
- Investment
- $6,500 for the MVP, $21,500 for the full product
- Run it
- Inside your business, or as part of your offer to clients
What it does
For design teams running frequent user tests, turn consented test recordings and task definitions into evidence-linked usability findings.
- Tag observed struggles.
- Link clips to tasks.
- Separate observation from inference.
- Group issues.
- Capture researcher judgments.
- Export findings.
What goes in, what comes out
- Consented test recordings
- Task definitions
AI drafts, people review. Research evidence workspace with reviewed deliverables.
- Evidence-linked usability findings
How it works
The workflow
- InStart with
Consented test recordings and task definitions
- 1
Agree the decision and research questions
- 2
Define permitted sources or participants
- 3
Collect evidence
- 4
Code findings
- 5
Compare supporting and contradictory material
- 6
Review interpretations
- 7
Deliver a cited brief with next questions
- OutFinish with
Evidence-linked usability findings
AI does the heavy lifting, people stay in charge
Assist with retrieval, transcription, structured extraction and thematic synthesis. Preserve source passages and methodological context. Human researchers validate inclusion, quotations and conclusions. Use real participants when customer research is required.
What your team sees
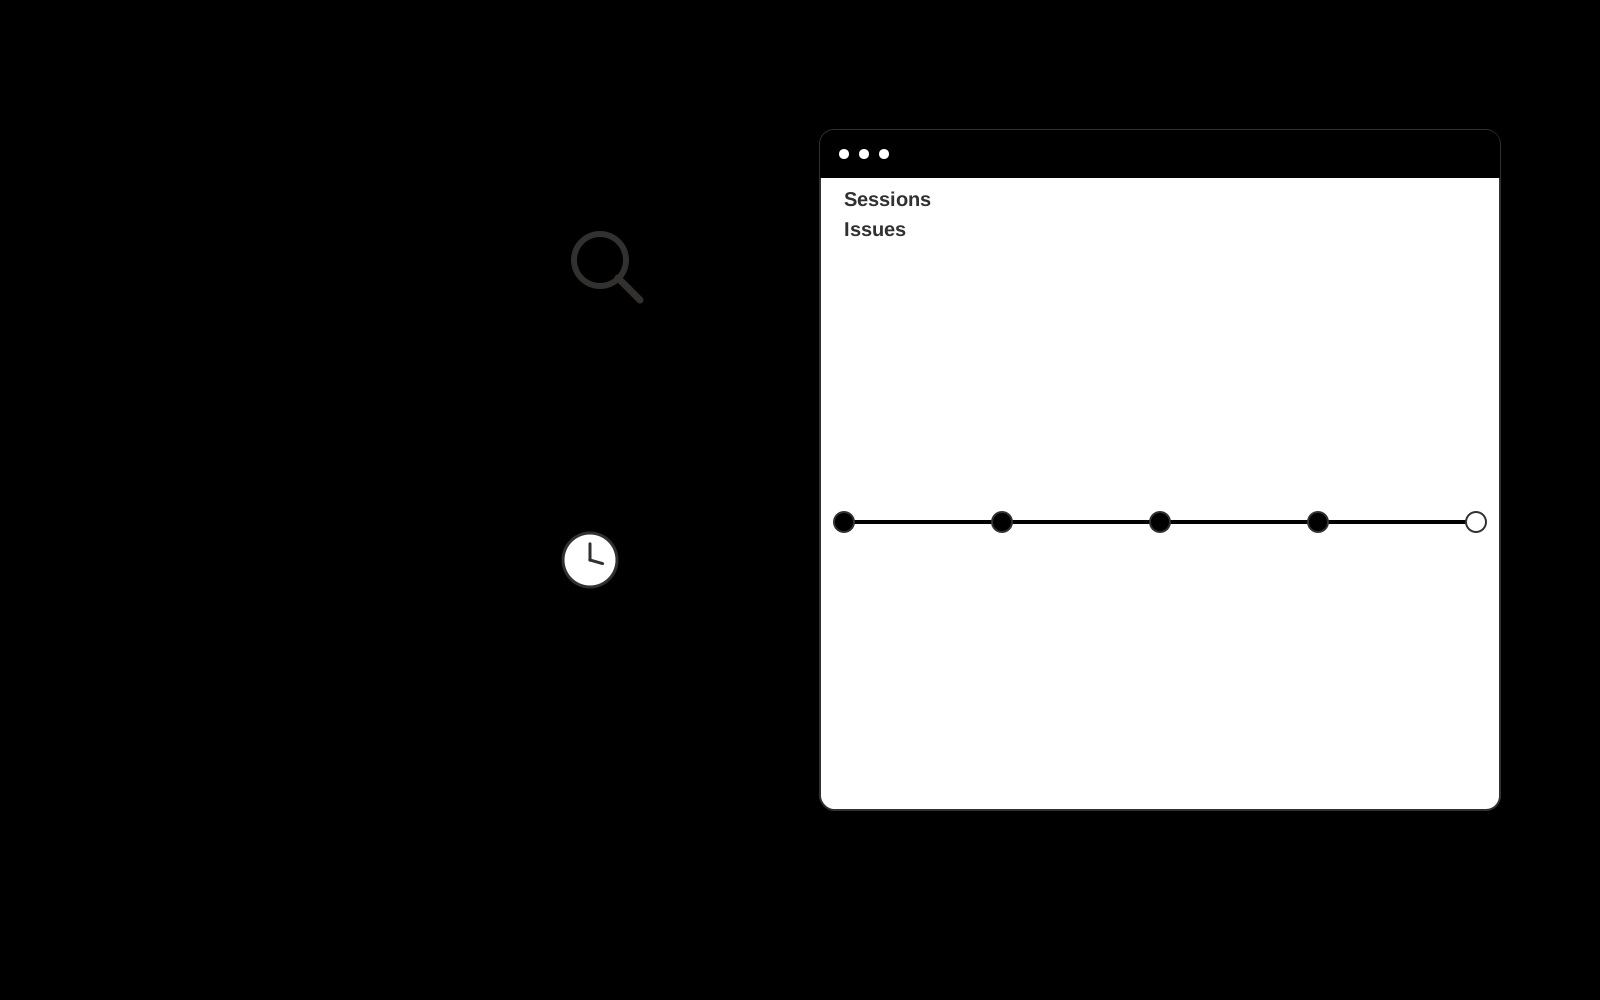
Key screens: Session timeline, issue evidence, findings board. Organize work by research question. Show a source library, an evidence matrix and a draft findings panel with linked quotations. Keep contradictory findings and unanswered questions visible. Allow reviewers to inspect the original context before accepting an interpretation. In this product, the first view is session timeline, followed by issue evidence and findings board.
Accounts and administration
Source provenance, participant consent where applicable, research questions, coding definitions, reviewer disagreements, citations and versioned conclusions.
Integrations and data access
Product feedback, authorized interviews, usage exports and requirement records. Permitted research libraries, interview recording imports, citation exports and document editors. Preserve original source metadata throughout the workflow. These are candidate integration categories, not verified supported connectors.
How we build it
We build with our own AI software development factory, so most implementations take days to a few weeks of creation time, not months. You see working software at every step, and exact timing depends on availability.
- 1
Scoping call
Day 1Thirty minutes on your process, your data and how you want to run it: for your own team, or for your clients. You get a fixed scope and price for the MVP.
- 2
MVP
3 daysOne buyer segment, one recurring use case; first modules: tag observed struggles; link clips to tasks. Manual review in the loop. Built by our AI software factory.
- 3
Paid pilot
4 daysAccounts, roles, review states, audit trail and the first integration, hardened for two to three paying pilot customers.
- 4
Full product
7 daysRemaining modules: group issues; capture researcher judgments; export findings. Self-serve onboarding, billing, monitoring and the wider integration set.
- 5
Run and improve
MonthlyWe host, monitor and improve it for a fixed monthly fee, or hand it over to your team. How the retainer works.
Why we start with an MVP
An MVP, or minimum viable product, is the smallest version that your users can actually work with. It is not a cheap version of the full solution. It is a test, built to answer the questions that decide whether the rest is worth building.
- Pick the riskiest assumption. Here: will design teams running frequent user tests use it to solve "session evidence is difficult to turn into actionable findings"?
- Build only what tests it. One team, one use case, a few core modules. People do the rest by hand for now.
- Run a paid pilot. Answer one practical question using a bounded evidence set.
- Measure, then decide. Track reviewer agreement and issues reproduced. Then expand, change course or stop, with evidence instead of opinions.
MVP scope for this solution. Begin with design teams running frequent user tests and one recurring use case. Build the first two modules: tag observed struggles; link clips to tasks. Provide operator assistance for the third module: separate observation from inference. Deliver evidence-linked usability findings through a manual review queue. Perform other necessary full-scope functions manually during the pilot. Include all applicable access, accuracy and professional-review controls from the start.
After the MVP. After paid pilots establish value, automate the remaining modules: group issues; capture researcher judgments; export findings. Add one validated source integration, reusable customer configuration and recurring delivery. Expand to additional teams, document formats or languages only after testing the new scope.
What the build depends on. A clear research protocol, source access, citation tracking and qualified interpretation. Interview work also needs relevant participants and consent management.
Investment
A planning range to start the conversation, not a quote. You pay per phase, so you can stop after the MVP.
- Phase 1
MVP
One buyer segment, one recurring use case; first modules: tag observed struggles; link clips to tasks. Manual review in the loop.
- Phase 2
Paid pilot
Accounts, roles, review states, audit trail and the first integration, hardened for two to three paying pilot customers.
- Phase 3
Full product
Remaining modules: group issues; capture researcher judgments; export findings. Self-serve onboarding, billing, monitoring and the wider integration set.
Indicative total, MVP to full product$21,500about 3 weeks of creation time · start with the MVP from $6,500
Running costs per month
A rough indication of monthly hosting and AI model costs once it is live, not tested. Real costs depend on usage, file sizes and the models chosen.
| Stage | Hosting and infrastructure | AI usage | Total per month |
|---|---|---|---|
| MVP and paid pilotabout 3 customers | $30–$60 | $80–$160 | $110–$220 |
| Full productabout 50 customers | $110–$210 | $880–$1,750 | $990–$1,960 |
Run it or resell it
For your own team
Design teams running frequent user tests run it inside the business: consented test recordings and task definitions in, evidence-linked usability findings out, reviewed by your people.
As part of your offer
Agencies, consultancies and software companies can offer it to their own clients under their brand. We build and maintain it; you sell and deliver it.
Your brand, or this one
Run it under your own brand, or start from this concept style.
- primary
#8a2791 - accent
#7dc954 - surface
#f0e4f1 - ink
#22201e
- Headings
- Archivo
- Text
- Lora
- Voice
- Curious, rigorous, user-led
Selling it to your own clients: the go-to-market playbook
Pricing to test
Test USD 750-3,000 for one tightly bounded research question and evidence pack. Participant recruitment, specialist review and licensed data are separately scoped. Repeat tracking can become a retainer. Prices are hypotheses.
Message to test
Usability research assistant for design teams running frequent user tests. Observed behavior and source clips remain attached to every usability finding. Demonstrate the claim through an annotated task-based usability report.
Where to find buyers
User research agencies
Lead magnet
An annotated task-based usability report
The first 30 days
- Week 1: interview five prospective buyers in this segment: design teams running frequent user tests. Ask to see a recent example of the problem and their current process.
- Week 2: prepare this demonstration using authorized or synthetic material: an annotated task-based usability report.
- Week 3: present it through user research agencies and seek one narrowly scoped paid pilot.
- Week 4: review reviewer agreement, issues reproduced, total delivery effort and a concrete renewal decision before increasing scope.
Paid pilot
Answer one practical question using a bounded evidence set. Ask a domain expert to review citations and reasoning, identify contrary evidence and assess whether the deliverable supports the intended decision. For this solution, use consented test recordings and task definitions and evaluate evidence-linked usability findings. Agree success thresholds with the buyer before starting; collect a baseline for reviewer agreement, issues reproduced. A positive signal is payment and repeat use with acceptable quality and delivery cost, not a favorable demo reaction alone.
Success metrics
Reviewer agreement, issues reproduced
Retention and expansion
Maintain the research question and evidence archive, offer follow-up studies and refresh important sources. Build repeat work around the buyer’s decision cycle.
Why clients would pick it
Niche research protocols, credible researcher relationships and a rights-cleared evidence archive with consistent interpretation methods. For this solution, build around observed behavior and source clips remain attached to every usability finding. This advantage requires execution and accumulated customer trust; the base model alone is not a defensible asset.
Alternatives and positioning
Research consultants, internal analysts, literature databases and general search or summarization tools. Differentiate on this specific proposed advantage: observed behavior and source clips remain attached to every usability finding. Test it against the buyer's current method on the same task. Competitor coverage and uniqueness have not been established.
Main delivery costs
Researcher time, source access, participant recruitment, transcription, evidence coding, expert review and report revisions.
Safeguards
Use consented research and preserve contradictory evidence. Separate observed user behavior, proposed explanations and untested product assumptions. Validate source access and reviewer availability during the pilot. Maintain customer-level access, data deletion controls and a record of final approvals.